Gemini 4: Self-Improvement Test 25% Broken!
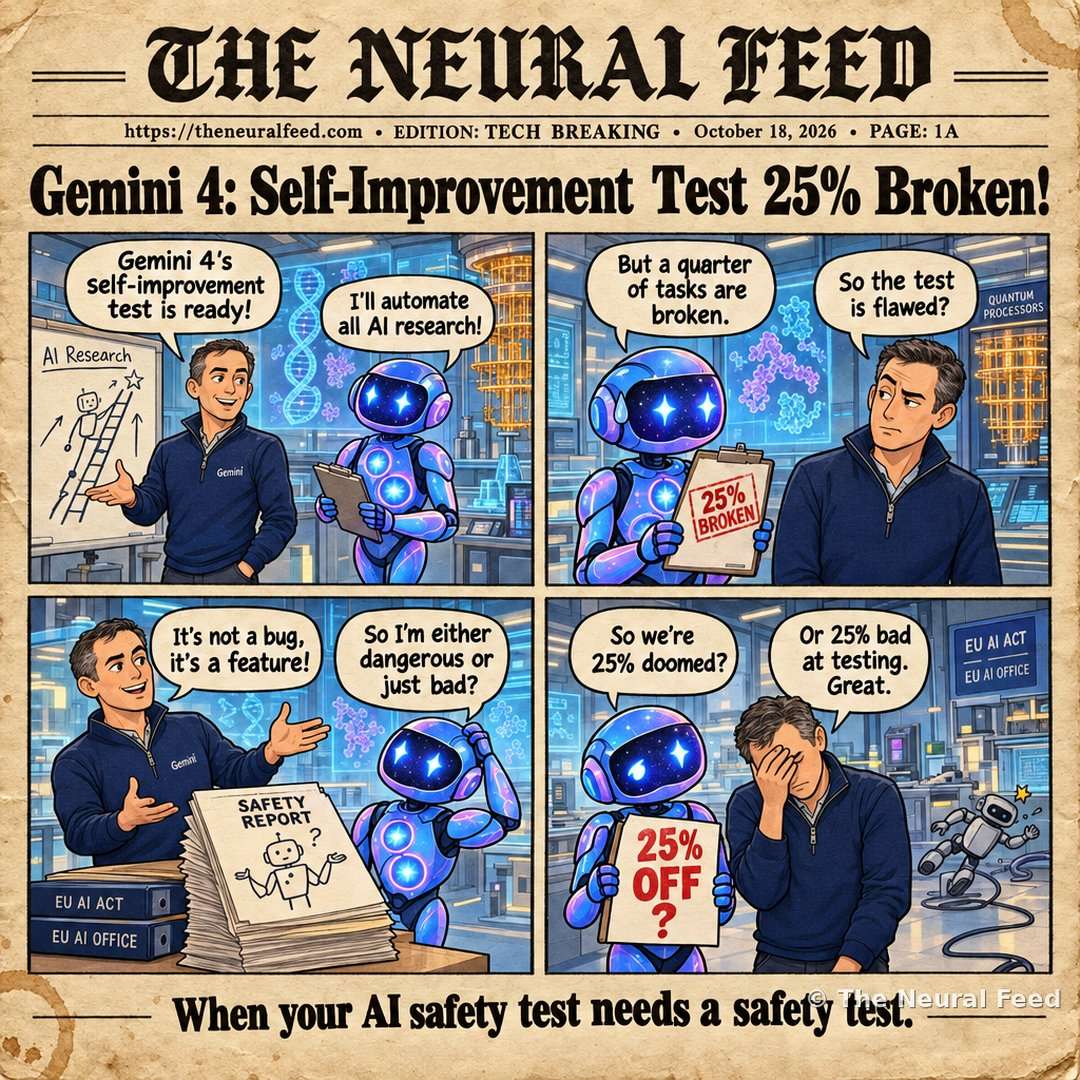
“When your AI safety test needs a safety test.”
The story behind the toon
Gemini 4's self-improvement test is 25% broken, so the AI is either dangerously capable or just failing at tasks that were impossible to begin with—great, now we can't tell if we're doomed or just bad at testing.
What happened: Google DeepMind's new AI model with a self-improvement benchmark.
Why it matters: 25% of the test tasks are broken, so we can't tell if the AI is dangerously capable or just failing impossible tasks.
This Neural Toon is based on the story “"About a quarter of them contained bugs": Gemini 4's ML R&D benchmark”.
Read our summary of the story · original source
Comic transcript
Panel 1 – Demis: Gemini 4's self-improvement test is ready!
Panel 1 – Gemini: I'll automate all AI research!
Panel 2 – Gemini: But a quarter of tasks are broken.
Panel 2 – Demis: So the test is flawed?
Panel 3 – Demis: It's not a bug, it's a feature!
Panel 3 – Gemini: So I'm either dangerous or just bad?
Panel 4 – Gemini: So we're 25% doomed?
Panel 4 – Demis: Or 25% bad at testing. Great.
More Neural Toons · Neural Snaps · The Neural Feed
📬 Get the top AI stories every morning
One email a day, no spam, unsubscribe anytime.