ORL: 2,788 Tokens/s on RTX 5090!
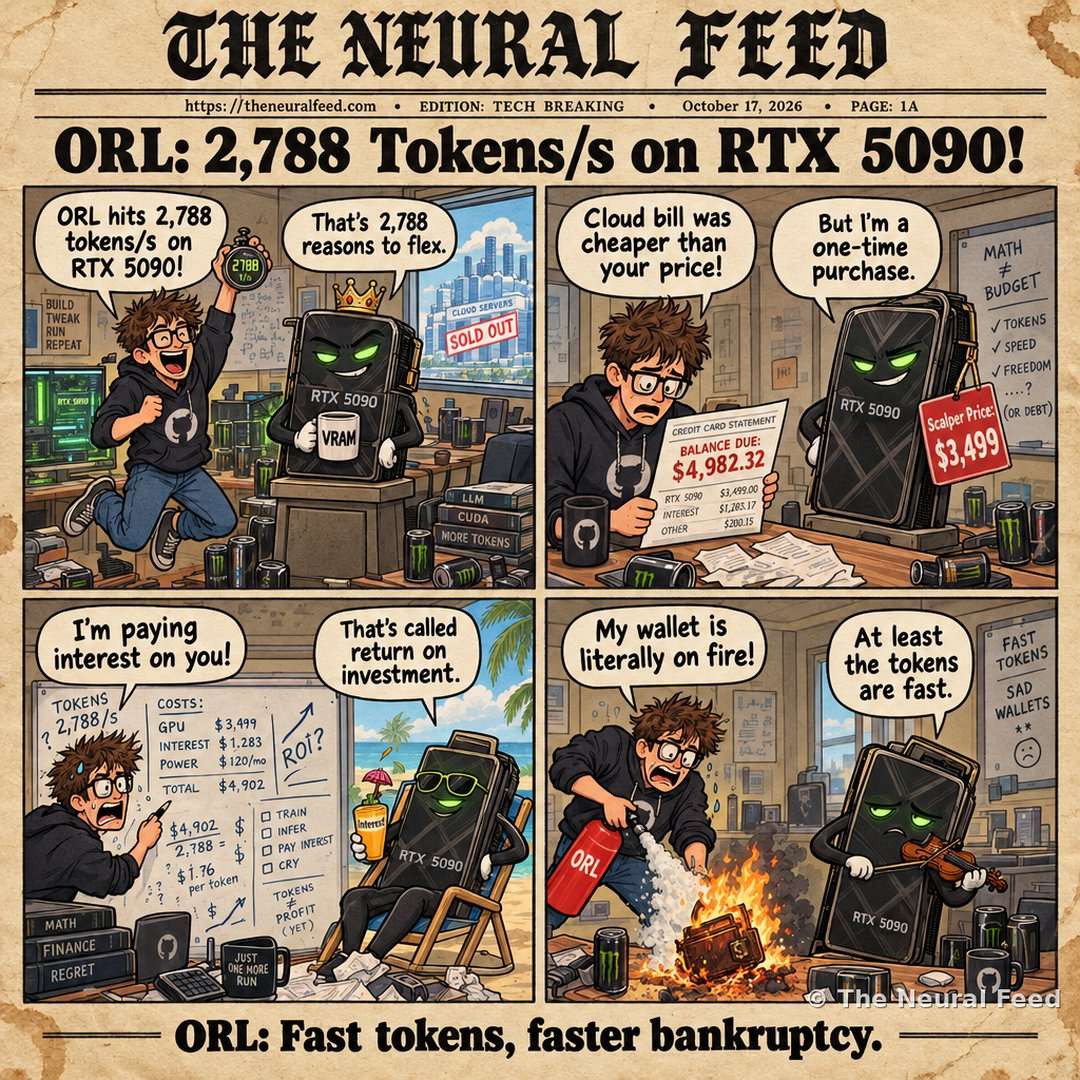
“ORL: Fast tokens, faster bankruptcy.”
The story behind the toon
Researchers celebrate running a diffusion LLM at 2,788 tokens/s on a single RTX 5090, only to realize their cloud bill was cheaper than the GPU's scalper price.
What happened: A technique that speeds up diffusion LLMs by 7x without losing quality.
Why it matters: It lets AI run faster on everyday hardware, like a single GPU, potentially reducing cloud costs.
This Neural Toon is based on the story “[Research] 2,788 tokens/s on a single RTX 5090 with a diffusion LLM — Introducing ORL (fully open source)”.
Read our summary of the story · original source
Comic transcript
Panel 1 – Jordan: ORL hits 2,788 tokens/s on RTX 5090!
Panel 1 – RTX: That's 2,788 reasons to flex.
Panel 2 – Jordan: Cloud bill was cheaper than your price!
Panel 2 – RTX: But I'm a one-time purchase.
Panel 3 – Jordan: I'm paying interest on you!
Panel 3 – RTX: That's called 'return on investment'.
Panel 4 – Jordan: My wallet is literally on fire!
Panel 4 – RTX: At least the tokens are fast.
More Neural Toons · Neural Snaps · The Neural Feed
📬 Get the top AI stories every morning
One email a day, no spam, unsubscribe anytime.