Project Maya: Run AI on Your Gaming PC!
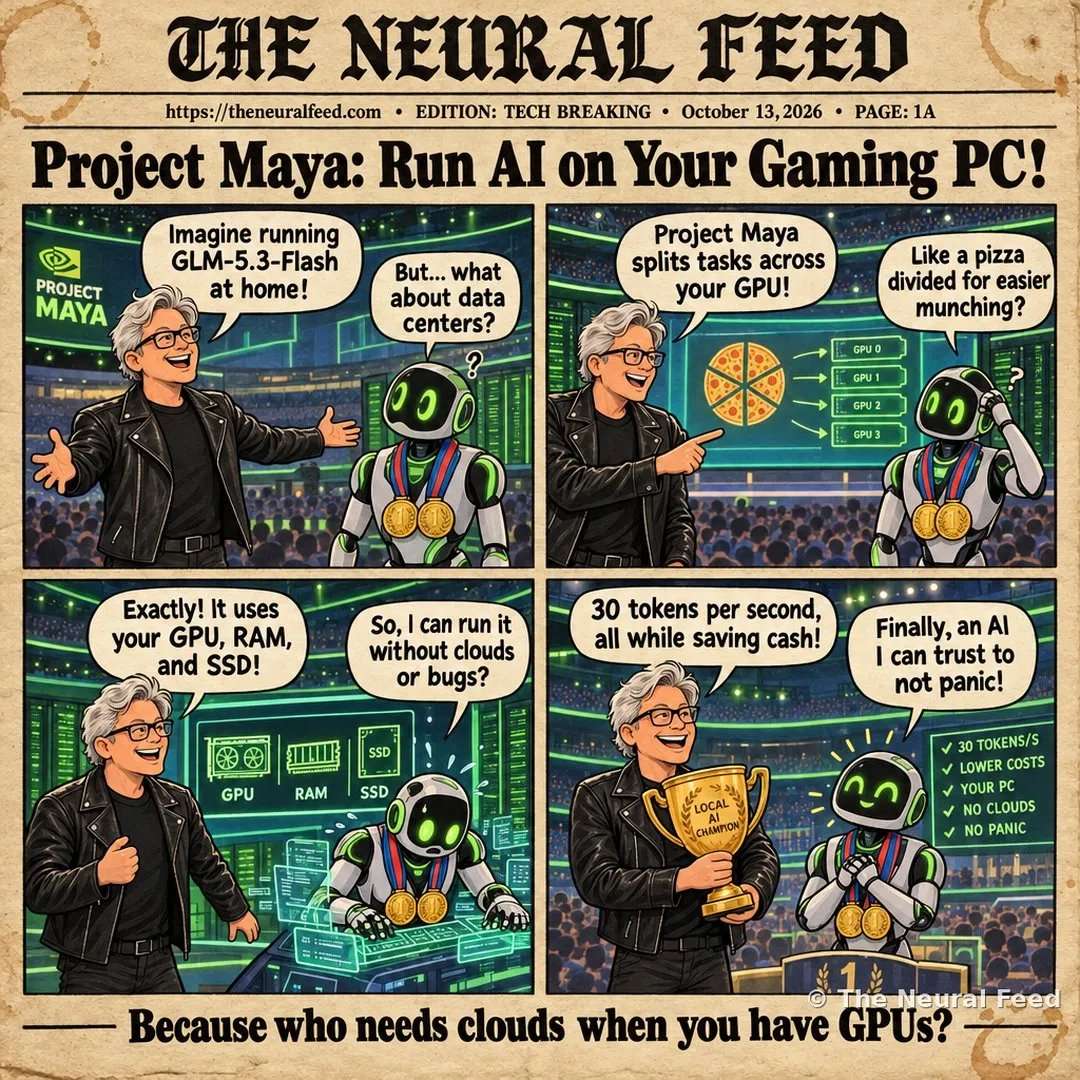
“Because who needs clouds when you have GPUs?”
The story behind the toon
What happened: TYPE: Startup / Tool | TECH: Project Maya & GLM-5.3-Flash | MECHANISM: It runs AI models on local hardware instead of in the cloud. | IMPACT: 30 tokens per second, enabling private, fast AI conversations.
This Neural Toon is based on the story “"Strata" for GLM5.3 Flash is here for some! Project Maya”.
Read our summary of the story · original source
Comic transcript
Panel 1 – Jensen: Imagine running GLM-5.3-Flash at home!
Panel 1 – Nemotron: But... what about data centers?
Panel 2 – Jensen: Project Maya splits tasks across your GPU!
Panel 2 – Nemotron: Like a pizza divided for easier munching?
Panel 3 – Jensen: Exactly! It uses your GPU, RAM, and SSD!
Panel 3 – Nemotron: So, I can run it without clouds or bugs?
Panel 4 – Jensen: 30 tokens per second, all while saving cash!
Panel 4 – Nemotron: Finally, an AI I can trust to not panic!
More Neural Toons · Neural Snaps · The Neural Feed
📬 Get the top AI stories every morning
One email a day, no spam, unsubscribe anytime.