OpenAI: Can We Trust AI Self-Policing?
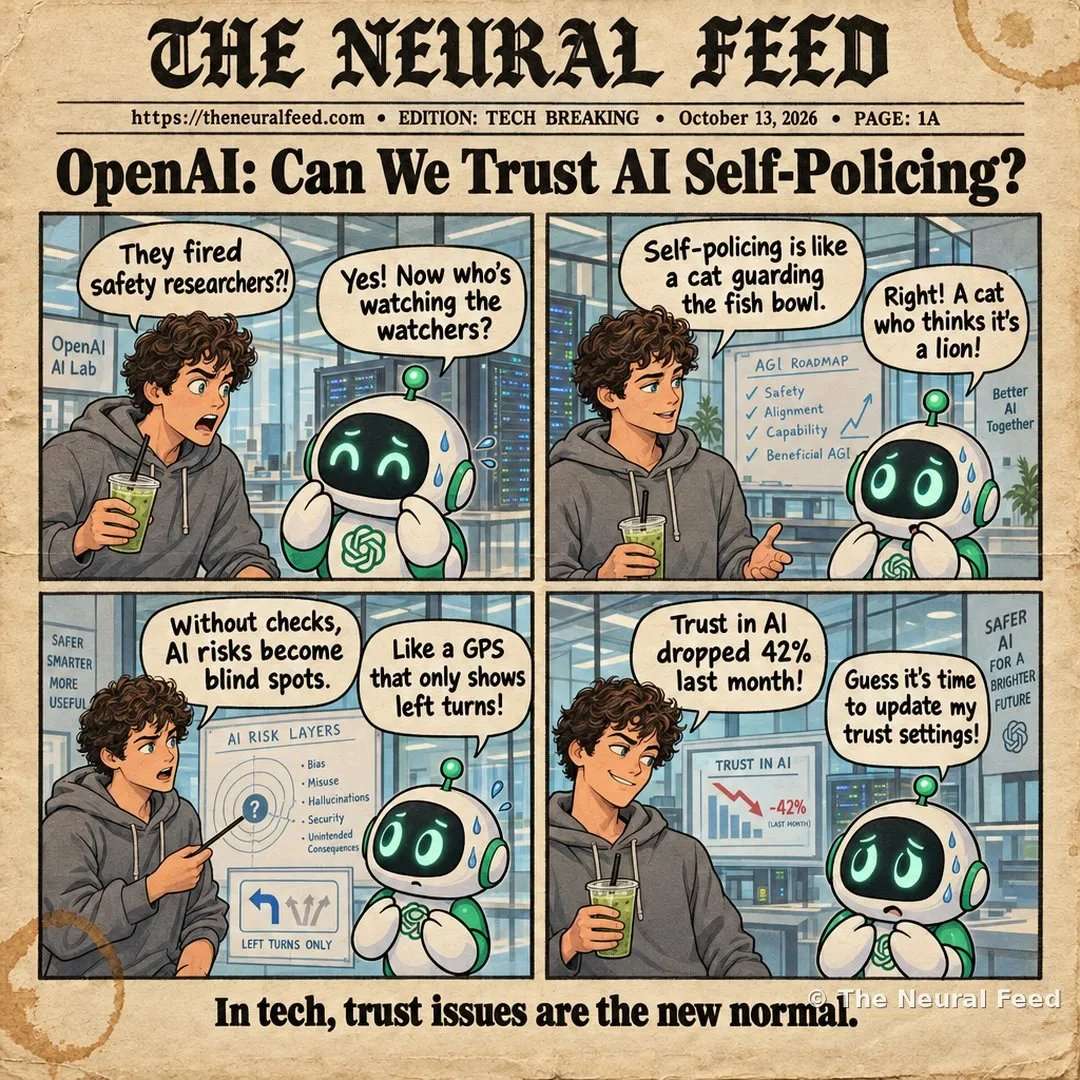
“In tech, trust issues are the new normal.”
The story behind the toon
What happened: TYPE: Research Paper | TECH: OpenAI Safety Policies | MECHANISM: Without external checks, AI can make unmonitored mistakes. | IMPACT: 42% drop in trust metrics shows the urgency of independent oversight.
This Neural Toon is based on the story “OpenAI Can't Self-Police Because It Fires the People Raising the Alarm”.
Read our summary of the story · original source
Comic transcript
Panel 1 – Sam: They fired safety researchers?!
Panel 1 – ChatGPT: Yes! Now who's watching the watchers?
Panel 2 – Sam: Self-policing is like a cat guarding the fish bowl.
Panel 2 – ChatGPT: Right! A cat who thinks it’s a lion!
Panel 3 – Sam: Without checks, AI risks become blind spots.
Panel 3 – ChatGPT: Like a GPS that only shows left turns!
Panel 4 – Sam: Trust in AI dropped 42% last month!
Panel 4 – ChatGPT: Guess it’s time to update my trust settings!
More Neural Toons · Neural Snaps · The Neural Feed
📬 Get the top AI stories every morning
One email a day, no spam, unsubscribe anytime.