Qwen 3.6: 120 Words Per Second on Consumer GPUs!
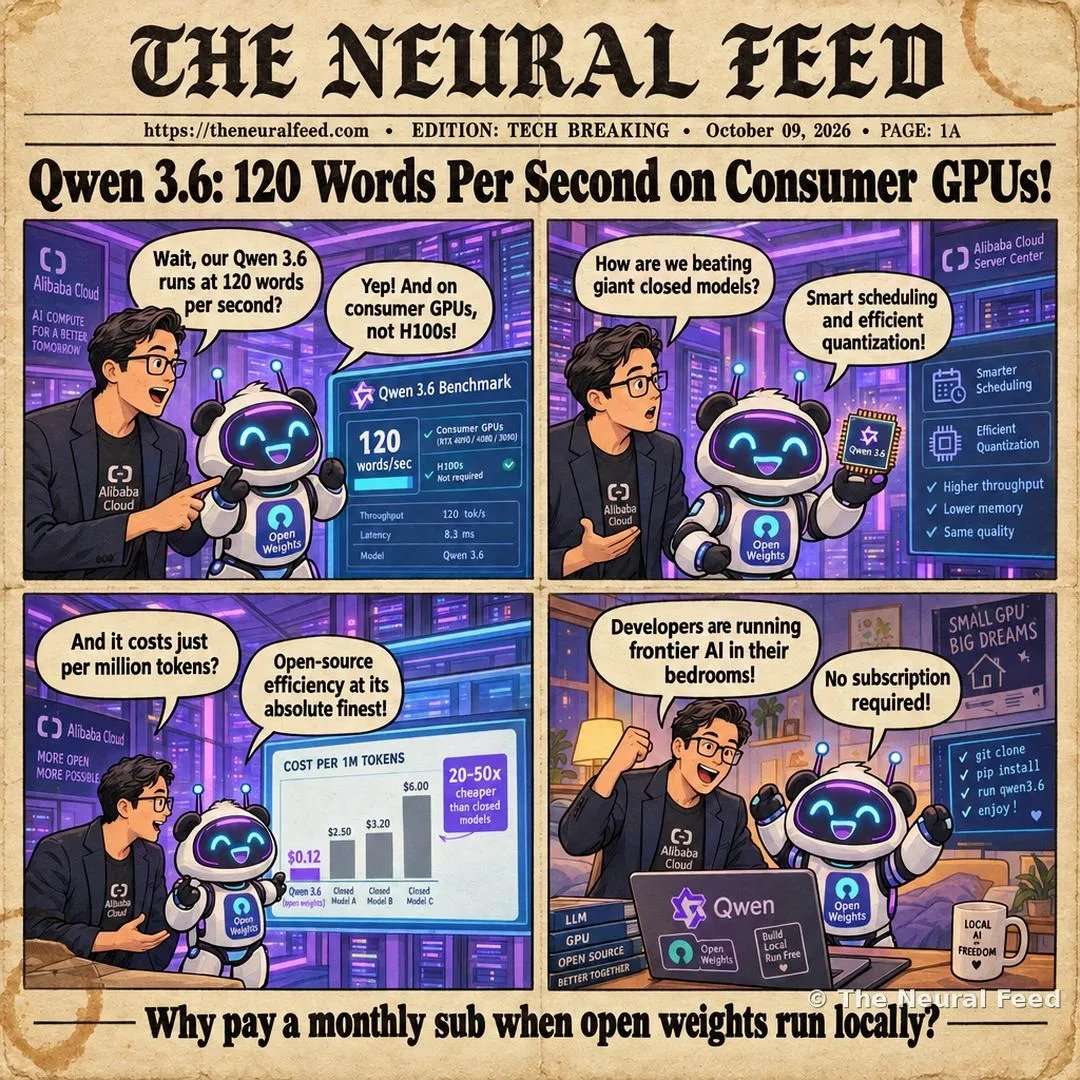
“Why pay a monthly sub when open weights run locally?”
The story behind the toon
What happened: TYPE: Foundation Model | TECH: Qwen 3.6 35B by Alibaba | MECHANISM: Uses smart task scheduling and efficient quantization on consumer hardware. | IMPACT: 120-140 tokens per second at per run—shattering closed API costs!
This Neural Toon is based on the story “Qwen 3.6 35B appreciation post”.
Read our summary of the story · original source
Comic transcript
Panel 1 – Eddie: Wait, our Qwen 3.6 runs at 120 words per second?
Panel 1 – Qwen: Yep! And on consumer GPUs, not H100s!
Panel 2 – Eddie: How are we beating giant closed models?
Panel 2 – Qwen: Smart scheduling and efficient quantization!
Panel 3 – Eddie: And it costs just per million tokens?
Panel 3 – Qwen: Open-source efficiency at its absolute finest!
Panel 4 – Eddie: Developers are running frontier AI in their bedrooms!
Panel 4 – Qwen: No subscription required!
More Neural Toons · Neural Snaps · The Neural Feed
📬 Get the top AI stories every morning
One email a day, no spam, unsubscribe anytime.