SynIL: Robots Learn From Your Botched TikToks!
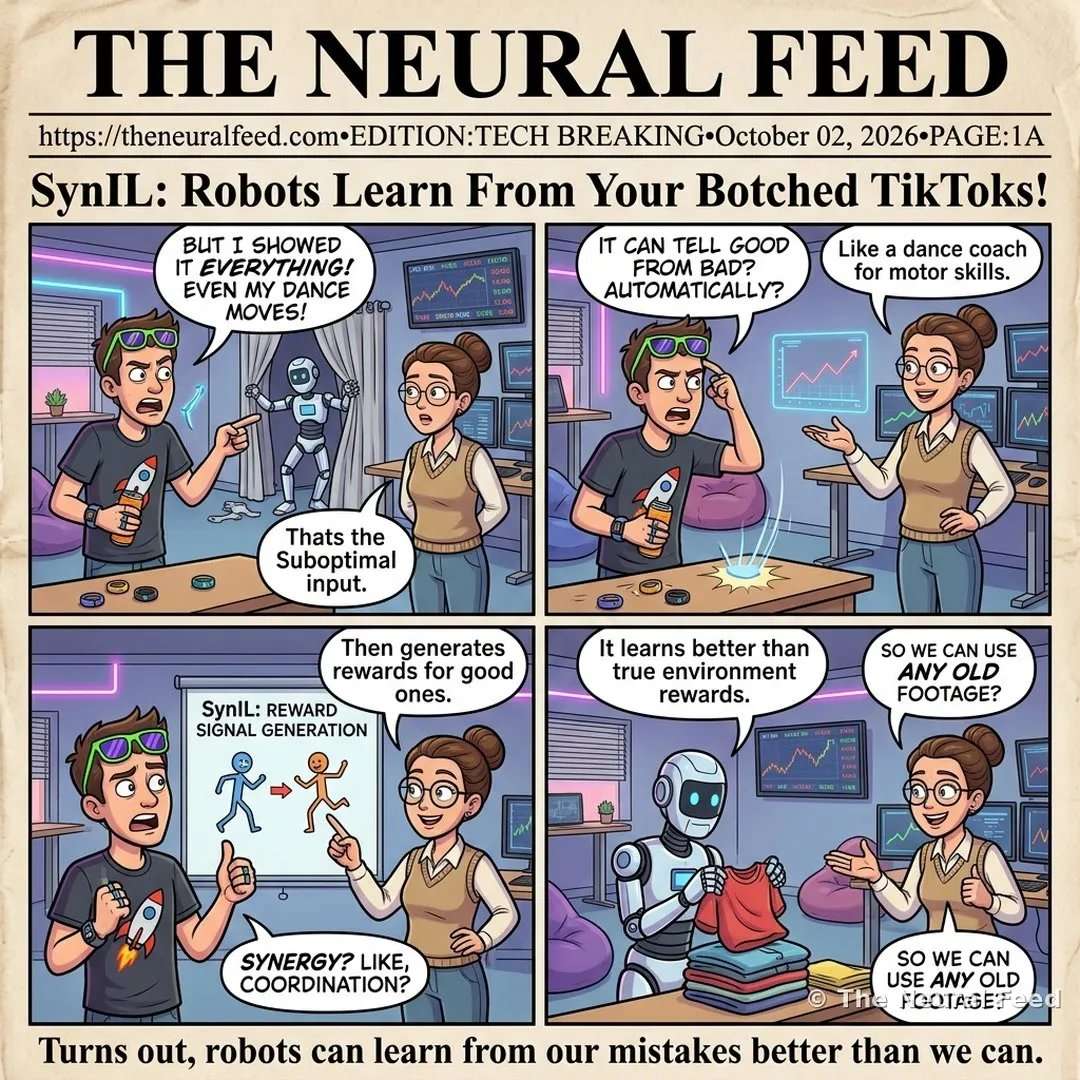
“Turns out, robots can learn from our mistakes better than we can.”
The story behind the toon
What happened: TYPE: Research Paper (arXiv) | TECH: SynIL (Synergy-based Imitation Learning) | MECHANISM: SynIL algorithmically quantifies 'motor synergy' – the low-dimensional coordinated structure in movement – to assess demonstration quality and generate dense, transition-level reward signals for robot training. | IMPACT: Substantially outperforms Behavior Cloning and achieves performance comparable to (and often superior to) offline reinforcement learning trained on true environment rewards, enabling robots to learn from cheap, imperfect demonstration datasets.
This Neural Toon is based on the story “SynIL: Leveraging Synergy for Offline Imitation Learning from Imperfect Demonstration Datasets”.
Read our summary of the story · original source
Comic transcript
Panel 1 – Sam: BUT I SHOWED IT EVERYTHING! EVEN MY DANCE MOVES!
Panel 1 – Casey: Thats the problem. Suboptimal input.
Panel 2 – Sam: IT CAN TELL GOOD FROM BAD? AUTOMATICALLY?
Panel 2 – Casey: Like a dance coach for motor skills.
Panel 3 – Casey: Then generates rewards for good ones.
Panel 3 – Sam: SYNERGY? LIKE, COORDINATION?
Panel 4 – Casey: It learns better than true environment rewards.
Panel 4 – Sam: SO WE CAN USE ANY OLD FOOTAGE?
More Neural Toons · Neural Snaps · The Neural Feed
📬 Get the top AI stories every morning
One email a day, no spam, unsubscribe anytime.